In my earlier series on analogy, I deliberately avoided high-level words like “understanding,” “cognition,” or “comprehension.” I wanted to stay close to concrete engineering realities — immutable snapshots, reconciliation, fire-and-forget data passing, declarative descriptions. That discipline revealed something useful: surface fluency (smooth, plausible mappings) is easy to achieve, while deeper mechanical reliability is much harder to verify.
This new series steps directly into the territory I previously bracketed. I want to examine what “understanding” actually means when we apply the term to monolithic large language models.
The word is everywhere in current discourse. Models are said to “understand” prompts, context, nuance, jokes, instructions, even emotions. Yet the moment we press on the claim, the conversation fragments. Some see genuine, if imperfect, comprehension. Others see sophisticated pattern completion and distributional mimicry. Both sides can point to impressive outputs; both can point to brittle failures.
This is not simply a matter of incomplete evidence or noisy benchmarks. It points to something deeper.
The Quinean Starting Point
In Word and Object (1960), W. V. O. Quine introduced the thesis of the indeterminacy of translation. Even when we have perfect access to all observable behavior — every utterance, every stimulus, every pattern of assent or dissent — multiple incompatible “translation manuals” can fit the data equally well. There is often no fact of the matter that decides which manual is uniquely correct.
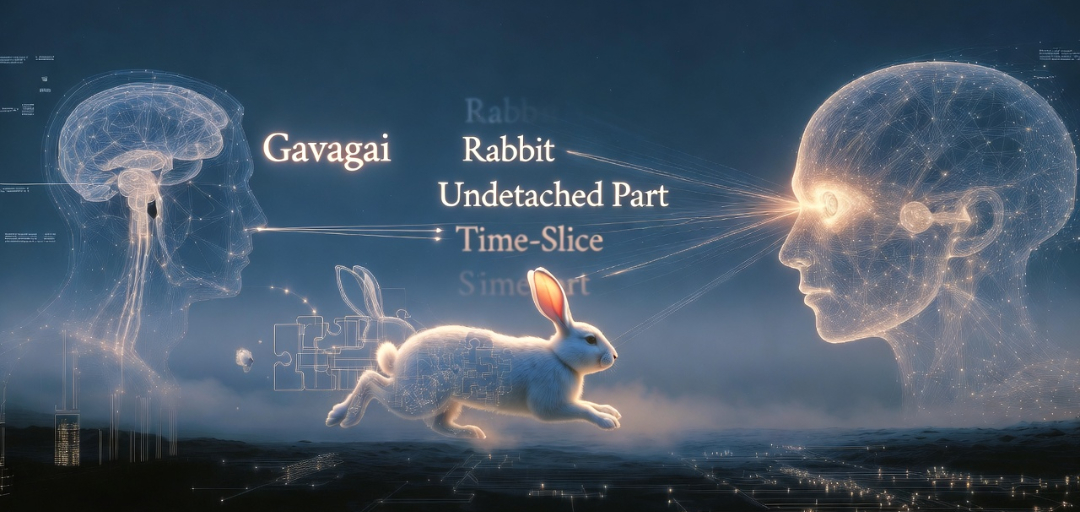
The famous “Gavagai” example captures the issue: a native utters “Gavagai!” as a rabbit runs by. The linguist’s behavioral evidence is consistent with translating it as “Rabbit,” “Undetached rabbit part,” or “Rabbit stage.” No amount of further pointing, querying, or observing settles the reference definitively. The raw data underdetermines the interpretation.
Now replace the jungle linguist with anyone (or any evaluation framework) trying to decide whether an LLM “understands” a piece of language. The observable evidence is sequences of tokens, activation patterns, benchmark scores, user ratings, and behavioral outcomes (does the output cohere? solve the task? generalize reasonably?).
Multiple interpretive manuals fit this same evidence:
- Functional / intentional manual: The model manipulates internal representations in context-sensitive, inferentially coherent ways that support reliable task completion and generalization. This looks like understanding.
- Statistical mimicry manual: The model performs sophisticated next-token prediction shaped by massive training correlations. What looks like understanding is high-fidelity behavioral simulation without stable reference, causal modeling, or genuine “aboutness.”
- Graded / use-based manual: Understanding is not binary or intrinsic but emerges relationally from how well the system participates in language games (Wittgensteinian) or proves predictively useful under the intentional stance (Dennettian).
Because the evidence is holistic and underdetermined, no purely empirical test can force one manual over the others. We choose (consciously or not) based on pragmatic factors: simplicity, conservatism, fit with our own conceptual scheme, and usefulness for our goals.
Why This Matters for Monolithic LLMs
Current transformer-based models are extraordinarily good at producing surface-level statistical coherence. They excel at fluent continuation, strong pattern matching, and distributional mimicry. This creates the illusion of smooth, reliable understanding — until we shift the distribution, demand counterfactual reasoning, or probe for stable internal structure.
Mechanistic interpretability work increasingly shows that what looks like “understanding” can arise from entangled features in superposition, shallow circuits, or sophisticated pattern completion rather than reusable algorithmic structures. At the same time, some circuits and linear representations do appear to track world states or causal relations in limited domains.
The Quinean lens does not resolve the debate. It reframes it productively: instead of asking the binary “Does the model understand?” we can ask sharper questions:
- Under which interpretive manual does the model’s behavior look like understanding, and what practical work does that manual let us do?
- Where do the rival manuals diverge in their predictions about robustness, generalization, and failure modes?
- What additional substrate properties or grounding mechanisms would be required to shrink the indeterminacy and move from behavioral adequacy toward more stable, compositional mechanical understanding?
The Road Ahead
This series will not attempt to deliver a final verdict on whether LLMs “truly understand.” That question, framed in Quinean terms, is largely ill-posed once all behavioral evidence is fixed. Instead, the series will audit “understanding” from multiple angles:
- Mechanistic interpretability: features, circuits, superposition, and what they actually represent.
- Philosophy of language applied to transformer internals: sense/reference, language games, and indeterminacy inside the residual stream.
- Cognitive science comparisons: schemas, mental models, causal vs. statistical reasoning.
- Engineering substrate limits: what attention and weights can and cannot easily do.
- Practical implications for safety, alignment, and future architectures.
The consistent thread will be the tension you already identified in the Analogy series: the gap between impressive surface fluency and verifiable mechanical reliability.
I invite you to read with both charity and skepticism — exactly the stance Quine forces us to adopt. The goal is not to win the “who is right?” game about LLM understanding, but to map the available manuals clearly, expose where they diverge, and ask what kind of system would make the indeterminacy smaller and the understanding more robust.
That is the new direction this series will explore.